One Shot Card, Three Prompt Orders: A Copy-Paste Template for Veo, Seedance and Kling
Three prompt guides for three AI video models give three different orders for the same ingredients. One says lead with the camera. One says lead with the subject. One says set the scene before the action. If you paste one prompt into all three, you are following at most one of those guides.
**Write the shot once as a card with fixed fields, then reorder the same fields for each model. Never rewrite the idea.**
This post gives you that card to copy, the reorder rule for Veo, Seedance and Kling, and a six-word cut list. It is a sourced synthesis of three public guides, not a quality test. We did not render these prompts across the models for this article, so nothing here claims one ordering produces better footage. Treat the ordering advice as a hypothesis to check in three takes, and we show you how.
## The Shot Card (copy this)
```
SHOT CARD
LENGTH: 5 s (start short, extend only after it works)
SUBJECT: [one fixed label, e.g. "the barista, 30s, green apron"]
ACTION: [one concrete verb + its physical result, e.g. "slides a cup across the counter, steam trails off"]
CAMERA: [one named move: slow push-in / dolly left / pan right / rack focus / locked-off]
SETTING: [place, time of day, light source]
LOOK: [optional: film stock, palette, lens]
AUDIO: [dialogue in "double quotes", named sounds tied to actions, ambience, or "no music"]
```
Fill every field with something you could point a camera or microphone at. If a field only contains a mood, it is empty.
## Why one prompt order does not fit all models
These are the three guides we compared, each read on October 20, 2026:
| Guide | Published | What it says about order |
|---|---|---|
| [Veo 3.1 prompt guide, LTX](https://ltx.io/blog/veo-prompt-guide) | Dec 23, 2025 | Formula: Camera + Subject + Action + Setting + Style and Audio. Earlier elements get more attention, so front-load what matters. 75 to 125 words is typical; it advises against going past 175. Put audio after the visuals with labels like "Audio:" or "SFX:". |
| [Seedance 2.0 prompting guide, fal](https://fal.ai/learn/tools/seedance-2-0-prompting-guide) | Jun 18, 2026 | Subject and motion are required. Environment, look, camera and audio are optional, added as the shot needs them. Spoken lines go in double quotes. Write "cut to" between shots. Say "no music" when you want none. |
| [Kling 3.0 prompting guide, fal](https://blog.fal.ai/kling-3-0-prompting-guide/) | Feb 5, 2026 | Define subjects first and keep them consistent. Set the scene (setting, lighting, sound) before the action and dialogue. Label each shot in a multi-shot prompt. Give every speaker a unique label, not a pronoun. |
Two things to notice. First, these are guides written by third parties (a video-tool vendor and an inference host), not model-maker documentation, so treat them as practitioner advice. Second, they genuinely disagree: the Veo guide opens with the camera, the Kling guide opens with the subject and the scene, and the Seedance guide only insists on subject and motion. That is why a single pasted prompt is a compromise.
What all three agree on is the stuff inside the fields. Concrete beats vague. The Seedance guide puts it bluntly: mood words like "beautiful" or "cinematic" give the model nothing it can point a camera at. The Veo guide lists "cool scene" and "nice lighting" under things not to write. The Kling guide warns against prompts that are only lists of visual traits.
## The reorder rule
Keep the card. Change only the order of the lines when you paste.
- **Veo 3.1 order:** CAMERA, SUBJECT, ACTION, SETTING, LOOK, then AUDIO labeled "Audio:". Trim to roughly 75 to 125 words.
- **Seedance 2.0 order:** SUBJECT, ACTION first. Add SETTING, LOOK and CAMERA only if the shot needs them. Quote dialogue. Add "no music" if you want silence under speech.
- **Kling 3.0 order:** SUBJECT, then SETTING and sound, then ACTION, then dialogue. In multi-shot prompts, number each shot and give it its own framing, subject and motion.
This ordering is our reading of the three guides above. It is an inference, not a measured result.
### The 3-take check (before you commit a whole video)
Pick the cheapest model that suits the shot. Run the same card twice in two orders (camera-first and subject-first) at the shortest length, three takes each. Count how many takes give you the framing you asked for. If both orders land equally, stop thinking about order and spend your time on the fields. Short clips are cheap; the [per-second price table](/blog/ai-video-cost-per-second-shorts-budget) shows how fast the gap grows when you extend.
## Six words to cut from every card
1. beautiful
2. cinematic
3. epic
4. stunning
5. high quality
6. amazing
The Seedance guide calls out mood words and quality tags specifically, and the Veo guide lists vague wording under things to avoid. Replace each with something visible: a lens, a light source, a named camera move.
## A filled-in example
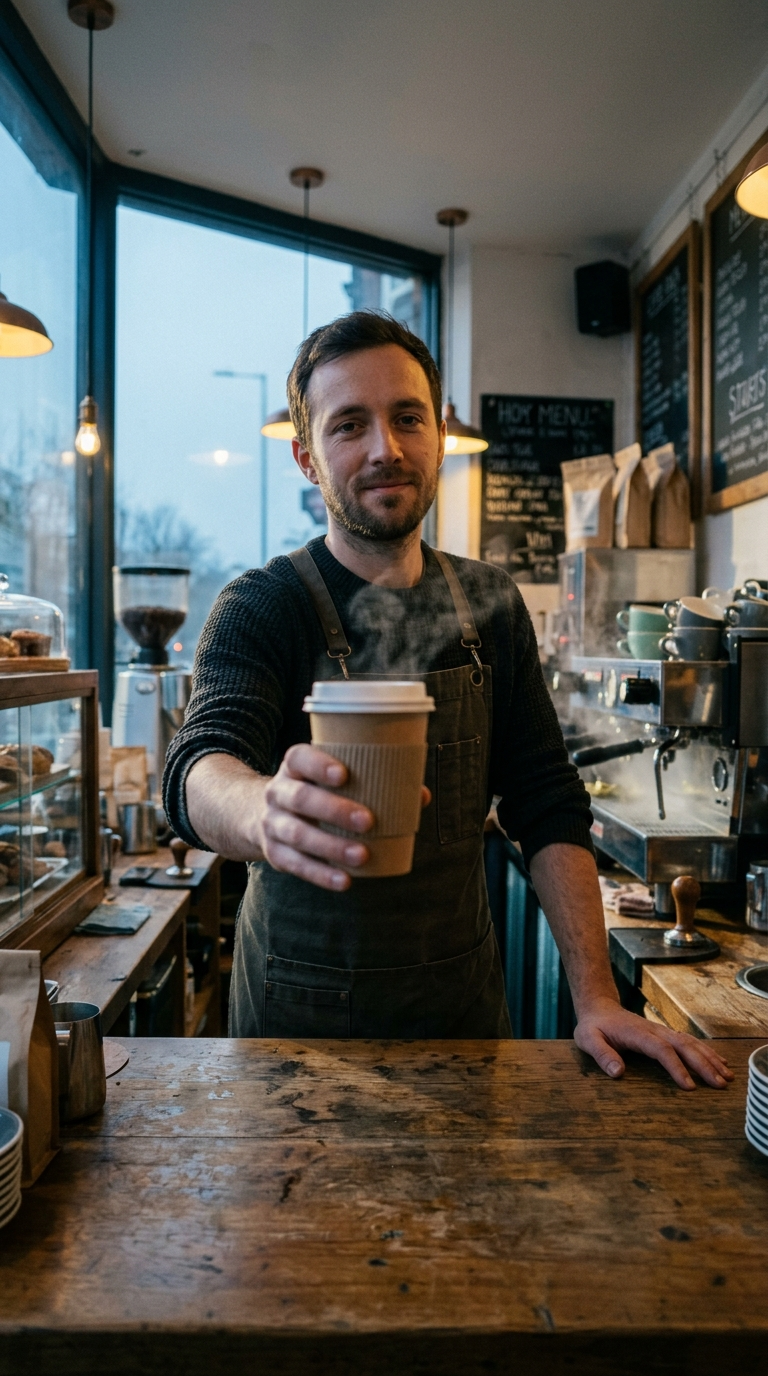
```
LENGTH: 5 s
SUBJECT: the barista, 30s, green apron
ACTION: slides a paper cup across the counter, steam trails off the lid
CAMERA: slow push-in
SETTING: small coffee shop, dawn, window light from the left
LOOK: warm palette, shallow depth of field
AUDIO: espresso machine hiss, cup scraping the counter, no music
```
Everything in that card is something you can see or hear. Nothing in it is a mood.
## Dialogue and multi-shot cards
Dialogue is where the three guides agree most. Put spoken lines in double quotes, keep them short, and cut between speakers instead of running a long monologue. For Kling, give each speaker a unique label and a voice description, and describe the action before the line so the model knows who is talking. For a multi-shot Short, write a card per shot and number them. The Seedance guide suggests "cut to" between shots in one prompt; the Kling guide describes up to six shots in a single generation.
## Where this fits in your workflow
A card is the cheap part. Before you spend on motion, check that the idea is worth a render, and that the script does not read like a template. Two of our other posts help here: [how to stop AI scripts sounding like AI](/blog/how-to-make-ai-scripts-not-sound-like-ai) and [why AI-generated faceless videos look fake](/blog/why-ai-generated-videos-look-fake). To choose the tool for a given job, see [AI Shorts generator: pick by the job](/blog/ai-shorts-generator-guide).
If you want to turn a card into a clip, you can generate stills and video from the same prompt inside [ClipNovia](https://clipnovia.io/?utm_source=blog&utm_medium=post&utm_campaign=ai-video-shot-card-prompt-template) and keep your cards in one place as you iterate.
## Limits of this post
We read three public guides on October 20, 2026 and combined them. We did not run controlled tests of ordering across models, so the reorder rule is a starting hypothesis. Model behavior changes with every release; recheck against the current docs of whichever model you use. Review again by 2026-11-20.
## FAQ
**Do I need a different prompt for every AI video model?**
Not a different idea. Keep one card and reorder its lines to match the guide for your model, as above.
**How long should an AI video prompt be?**
The Veo guide cited above says 75 to 125 words is typical and advises against exceeding 175. The Seedance guide recommends starting with 5-second clips to test style cheaply.
**Should I include audio in the prompt?**
If the model generates sound, yes. Name specific sounds tied to visible actions, put dialogue in double quotes, and say "no music" if you want none.
**What if my prompt keeps coming out wrong?**
Change one field at a time. If the shot still fails after three takes, the field is probably vague. Replace any mood word with something you can point a camera at.